
Placing File Records on Disk
The previous section stopped at the block — the unit the disk hands to main memory. This section goes one level up: how the DBMS lays records inside those blocks.
Records and Record Types
Definition — Record
A record is a collection of related data values (field values), each value belonging to a field (attribute).
Definition — Record type
A record type (or record format) is the definition of that collection: the sequence of field names together with their data types.
- A data type — integer, float, string of fixed length, Boolean, date/time — determines the number of bytes a field occupies and how those bytes are interpreted.
- A BLOB (Binary Large Object) holds unstructured data (images, video, documents, source code). BLOBs are usually stored apart from the record, in their own blocks; the record keeps only a pointer to them, so scanning the file doesn't drag megabytes of images through the buffer pool.
Files, Fixed-Length and Variable-Length Records
Definition — File
A file is a sequence of records.
If every record in the file has the same size in bytes, the file is made of fixed-length records; otherwise it has variable-length records.
Why records become variable-length
- Variable-length fields — e.g.
VARCHAR(50): only the characters actually stored take space. - Repeating fields (multivalued) — a record holds a varying number of values for one field.
- Optional fields — a field is present in some records and absent in others.
- Mixed record types — one file deliberately stores records of different types (common when related records are clustered together).
Because the reader can no longer compute "field 3 starts at byte 40", variable-length records need extra machinery:
| Technique | How it works | Cost |
|---|---|---|
| Separator characters | A special character marks the end of each variable field (and another marks the end of the record) | 1 byte per field; the character must never appear in the data |
| Length prefix | Each variable field is preceded by its length in bytes | Compact, no forbidden characters |
fieldname = value pairs | Store the field's name (or a short code) with each value | Self-describing — the natural choice for optional fields, but the most space |
| Null indicator / bitmap | One bit per nullable field says whether the value is present | Cheap way to encode NULL without a full name-value pair |
Fixed-length records are so much easier to process — position of field i is a constant offset, record j starts at byte
j × R— that systems sometimes pad variable-length fields to their maximum size and accept the wasted space.
Record Blocking
Records are stored inside blocks, so the DBMS must decide how many records fit and what happens to a record that straddles a block boundary.
Definition
The blocking factor bfr is the average number of records per block.
For a block of size B bytes and fixed-length records of size R bytes (with R ≤ B):
And a file of r records needs
Those leftover bytes are the reason for the spanned/unspanned choice:
| Organization | Rule | Consequence |
|---|---|---|
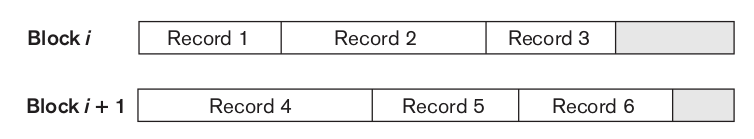
| Unspanned | A record never crosses a block boundary; leftover bytes stay unused | Simplest and fastest — a record is always read with one block access. Wastes up to R − 1 bytes per block. Impossible if R > B |
| Spanned | A record may be split across two blocks, with a pointer at the end of the first block to the block holding the rest | No wasted space, and required when R > B (e.g. long text). A spanned record costs two block accesses |
Unspanned — every record lies wholly inside one block, and the tail of each block (shaded) is left unused:
Spanned — record 4 is split across the two blocks, and a pointer P at the end of each block points to the block holding the remainder:
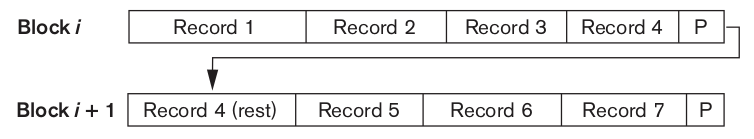
- Fixed-length records are normally stored unspanned; variable-length records are commonly stored spanned so no space is lost.
- For variable-length records
bfris an average, computed from the average record size — the formulas above then give expected values, not exact ones.
Allocating File Blocks on Disk
The blocks of one file must be placed somewhere on the device, and the placement decides whether "read the next block" is cheap.
| Allocation | Idea | Trade-off |
|---|---|---|
| Contiguous | Consecutive file blocks occupy consecutive disk blocks | Fastest sequential read (double buffering works perfectly); but expanding the file is hard |
| Linked | Each block contains a pointer to the next block of the file | Easy to grow the file anywhere; sequential reading is slow (no locality) |
| Linked clusters (extents / segments) | Allocate contiguous groups of blocks (a cluster), and link the clusters together | The usual compromise — locality inside a cluster, flexibility between clusters |
| Indexed | One or more index blocks hold the addresses of the file's blocks | Direct access to any block; costs an extra lookup and index storage |
File Headers
Definition
The file header (file descriptor) is information about the file, stored with it: the disk addresses of its blocks, the record format description (field lengths, field order, record type codes, separator characters, whether records are spanned).
A program that wants a record reads the header first — it needs the format description to know where the fields are inside the raw bytes, and the block addresses to know which blocks to fetch. Searching for a record means transferring blocks into buffers and scanning them in memory; when the required block address cannot be determined in advance, the search degrades into a linear search through the file's blocks. Reducing the number of blocks transferred is the entire purpose of the file organizations and indexes that follow.
Operations on Files
Operations on files fall into two groups (in practice they are mixed — a modification is a retrieval followed by an update):
- Retrieval — locate records and copy them into buffers so the program can examine them; the file on disk is unchanged.
- Update — insert, delete, or modify records, which changes blocks and forces them to be written back to disk.
A record is normally selected by a selection condition (a simple condition compares one field to a constant, e.g. SSN = '123456789'; a complex condition combines several with AND/OR/NOT). Most low-level file operations work on one record at a time, so the system keeps track of the current record — the one most recently located — and navigates relative to it.
| Operation | Meaning |
|---|---|
| Open | Prepare the file for access: read the header, allocate buffers, set the current record pointer to before the first record |
| Reset | Move the current-record pointer back to the beginning of the file |
| Find (Locate) | Search for the first record satisfying a condition, transfer its block into a buffer, and make it the current record |
| Read (Get) | Copy the current record from the buffer into a program variable, and (usually) advance the pointer |
| FindNext | Search for the next record satisfying the same condition; fetch its block if it isn't already buffered |
| FindAll / Scan | Locate all records satisfying a condition |
| FindOrdered | Retrieve all matching records in a specified order of some field |
| Insert | Add a new record: find the block where it belongs, put the record there, write the block back |
| Delete | Remove the current record: read its block, remove the record (or mark it deleted), write the block back |
| Modify | Change field values of the current record and write its block back |
| Reorganize | Rearrange the whole file — e.g. sort it, or compact it to reclaim the space of deleted records |
| Close | Release buffers and finish access to the file |
File organization vs. access method
File organization is how the records are physically arranged (unordered, ordered, hashed…). An access method is the set of programs/algorithms used to reach those records. Several access methods can apply to the same organization, and some access methods (like an index) apply to files organized in several ways — which is why the two terms are distinguished but often blurred in practice.
Static vs dynamic files
A static file is rarely updated after loading (e.g. an archive); a dynamic file changes constantly. The right organization depends on the mix: an organization that makes retrieval fast (a sorted file) may make insertion painfully slow, which matters only if the file is dynamic. The next note compares exactly this trade-off for heap and sorted files.